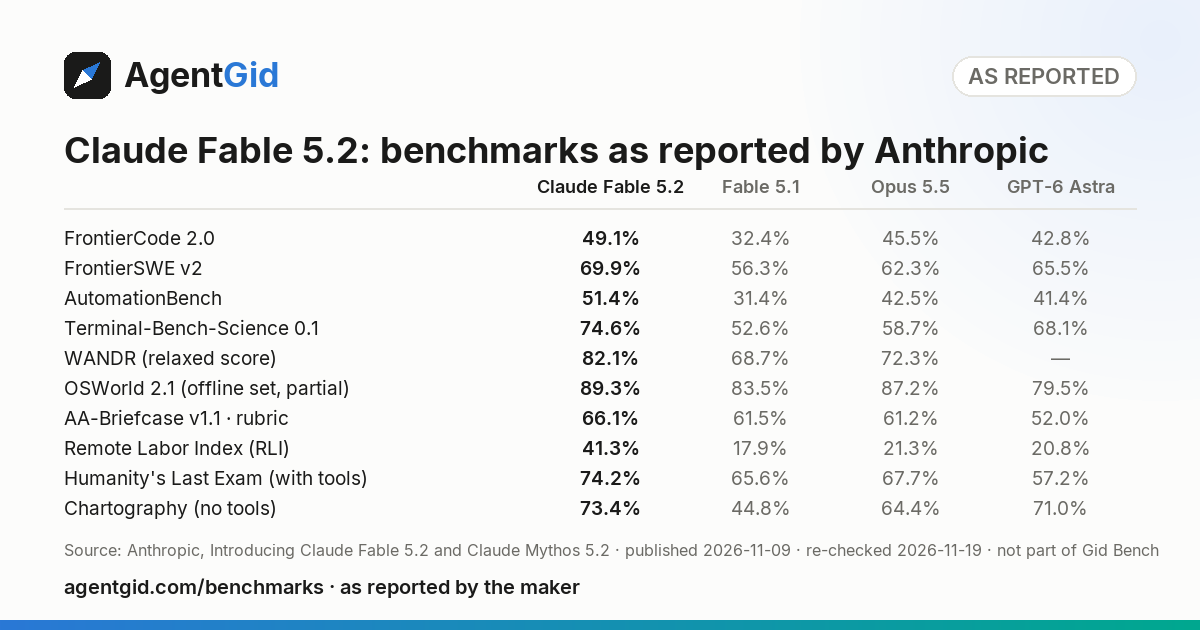
Claude Fable 5.2: benchmarks as reported by Anthropic
The launch table Anthropic published for Claude Fable 5.2 on Nov 9, 2026, re-checked against the page daily. Independent results for Claude Fable 5.2 on the benchmarks hub as they appear.
Claude Fable 5.2: benchmarks as reported by Anthropic
From Introducing Claude Fable 5.2 and Claude Mythos 5.2, published Nov 9, 2026. Each number was re-read on that page on Nov 19, 2026.
| Benchmark | Claude Fable 5.2 | Fable 5.1 | Opus 5.5 | GPT-6 Astra | Gemini 4 Carbon |
|---|---|---|---|---|---|
| Agentic coding | |||||
| FrontierCode 2.0 | 49.1% | 32.4% | 45.5% | 42.8% | 41.1% |
| FrontierSWE v2 | 69.9% | 56.3% | 62.3% | 65.5% | 61.2% |
| Business workflows | |||||
| AutomationBench | 51.4% | 31.4% | 42.5% | 41.4% | 53.9% |
| Agentic scientific research | |||||
| Terminal-Bench-Science 0.1 | 74.6% | 52.6% | 58.7% | 68.1% | 64.8% |
| Agentic search | |||||
| WANDR (relaxed score) | 82.1% | 68.7% | 72.3% | — | — |
| Computer use | |||||
| OSWorld 2.1 (offline set, partial) | 89.3% | 83.5% | 87.2% | 79.5% | 81.5% |
| Knowledge work | |||||
| AA-Briefcase v1.1rubric | 66.1% | 61.5% | 61.2% | 52.0% | 61.8% |
| Remote Labor Index (RLI) | 41.3% | 17.9% | 21.3% | 20.8% | — |
| Multidisciplinary reasoning | |||||
| Humanity's Last Exam (with tools) | 74.2% | 65.6% | 67.7% | 57.2% | — |
| Visual chart recognition | |||||
| Chartography (no tools) | 73.4% | 44.8% | 64.4% | 71.0% | 72.5% |