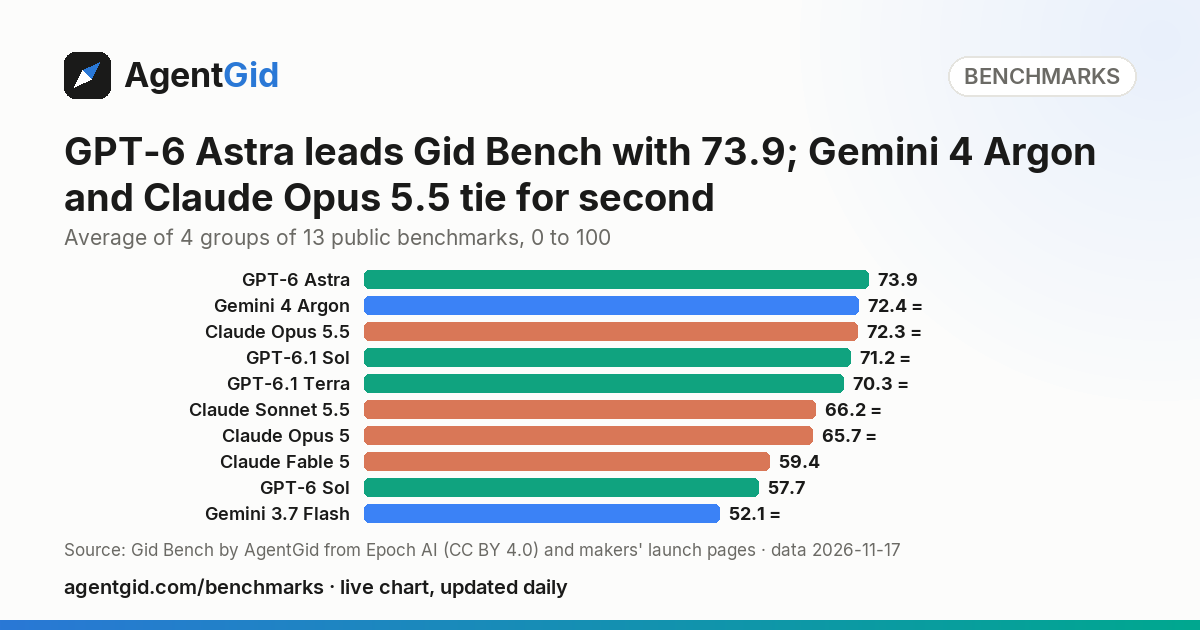
GPT-6 Astra leads Gid Bench with 73.9; Gemini 4 Argon and Claude Opus 5.5 tie for second
Average of 4 groups of 13 public benchmarks, 0 to 100. Live chart from AgentGid, updated daily.
GPT-6 Astra leads Gid Bench with 73.9; Gemini 4 Argon and Claude Opus 5.5 tie for second
Average of 4 groups of 13 public benchmarks, 0 to 100
Put this chart on your site
The chart updates by itself. Please keep the link to the source.
More charts
- Claude Opus 5.5 is best at coding with 71.1, 4.2 ahead of Claude Sonnet 5.5
- Gemini 4 Carbon is best at agents and long tasks with 76.0, 4.4 ahead of Gemini 4 Argon
- Claude Fable 5.2 is best at math and reasoning with 93.3, 3.1 ahead of GPT-6 Astra
- Claude Fable 5.2 is best at knowledge with 94.8, 6.3 ahead of Gemini 4 Carbon
- GPT-6.1 Sol is within 2.7 points of the top for 5x less
- Open models trail closed ones by 2.3 points on GPQA Diamond
- People's blind votes: Gemini 4 Carbon (High) leads, statistically tied with 2 other models
- Same model, different agent: up to 8 points apart (Gemini 3 Pro)
- Agent Arena: Claude Fable 5.2 (Max) leads, clear of the rest
- AI music with vocals: Lyria 3 Pro leads, clear of the rest
- AI music instrumental: Lyria 3 Pro leads, statistically tied with 1 other
- All benchmarks · Gid Bench, test by test